This article is part of the series “Sorting Algorithms: Ultimate Guide” and...
- explains how Bubble Sort works,
- presents the Bubble Sort source code,
- explains how to derive its time complexity
- and checks whether the measured runtime of the implementation matches the behavior the time complexity predicts.
You can find the source code for all articles in this series in my GitHub repository.
Bubble Sort Algorithm
With Bubble Sort (sometimes “Bubblesort”), two successive elements are compared with each other, and – if the left element is larger than the right one – they are swapped.
These comparison and swap operations are performed from left to right across all elements. Therefore, after the first pass, the largest element is positioned on the far right. Or better: at the latest after the first pass – it may have arrived there before.
You repeat this process until there is no more swapping in one iteration.
Bubble Sort Example
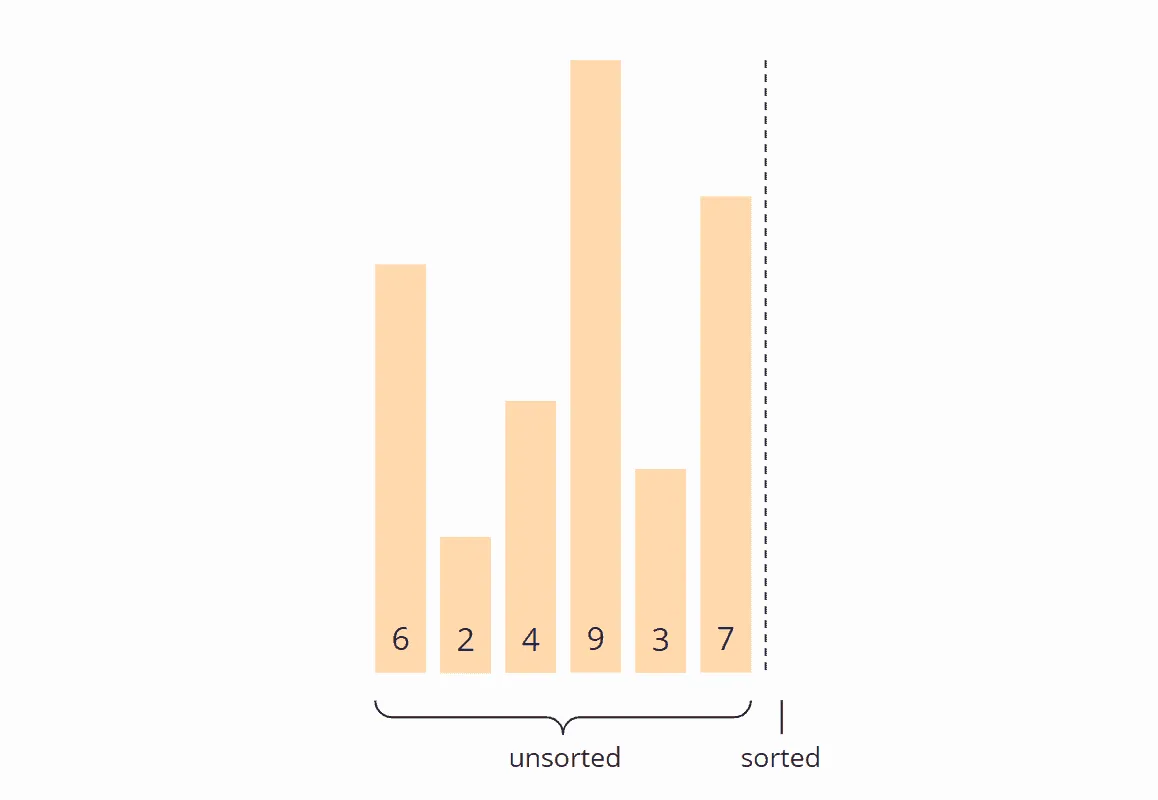
In the following visualizations, I show how to sort the array [6, 2, 4, 9, 3, 7] with Bubble Sort:
Preparation
We divide the array into a left, unsorted – and a right, sorted part. The right part is empty at the beginning:
Iteration 1
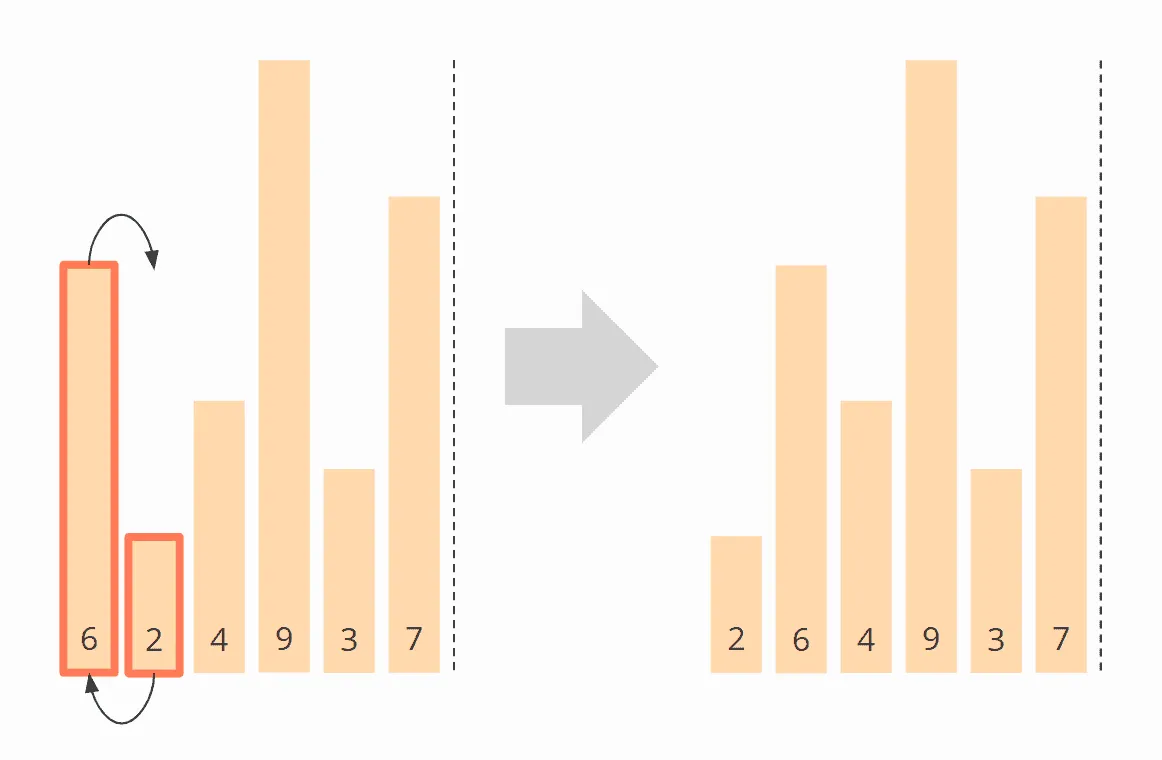
We compare the first two elements, the 6 and the 2, and since the 6 is larger, we swap the elements:
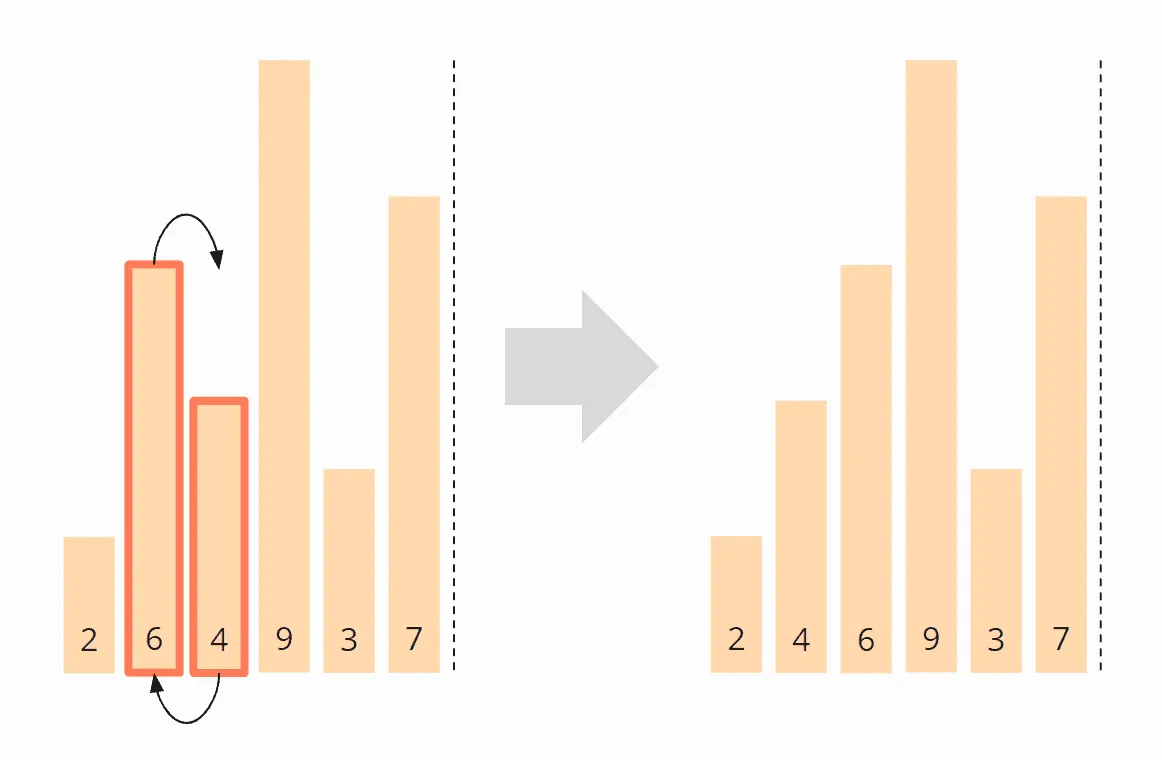
Now we compare the second with the third element, i.e., the 6 with the 4. These are also in the wrong order and are, therefore, swapped:
We compare the third with the fourth element, i.e., the 6 with the 9. The 6 is smaller than the 9, so we do not need to swap these two elements.
The fourth and fifth element, the 9 and the 3, need to be swapped again:
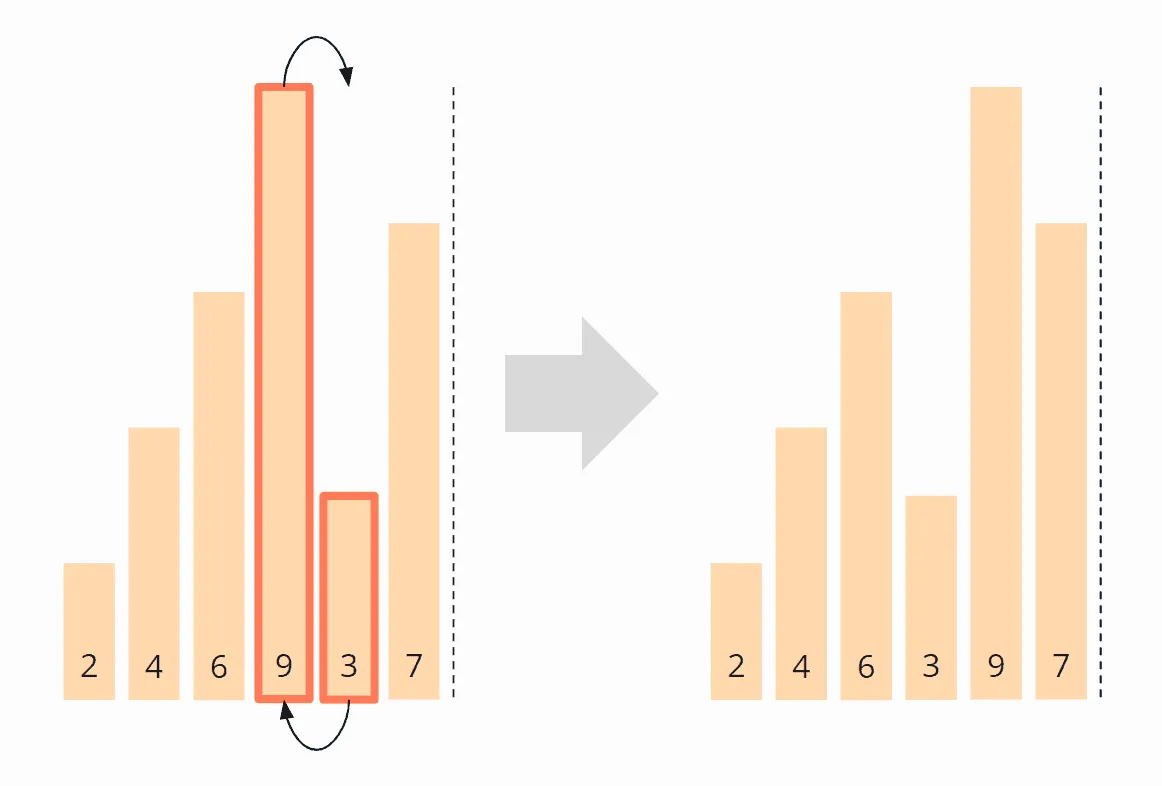
And finally, the fifth and sixth elements, the 9 and the 7, must be swapped. After that, the first iteration is finished.
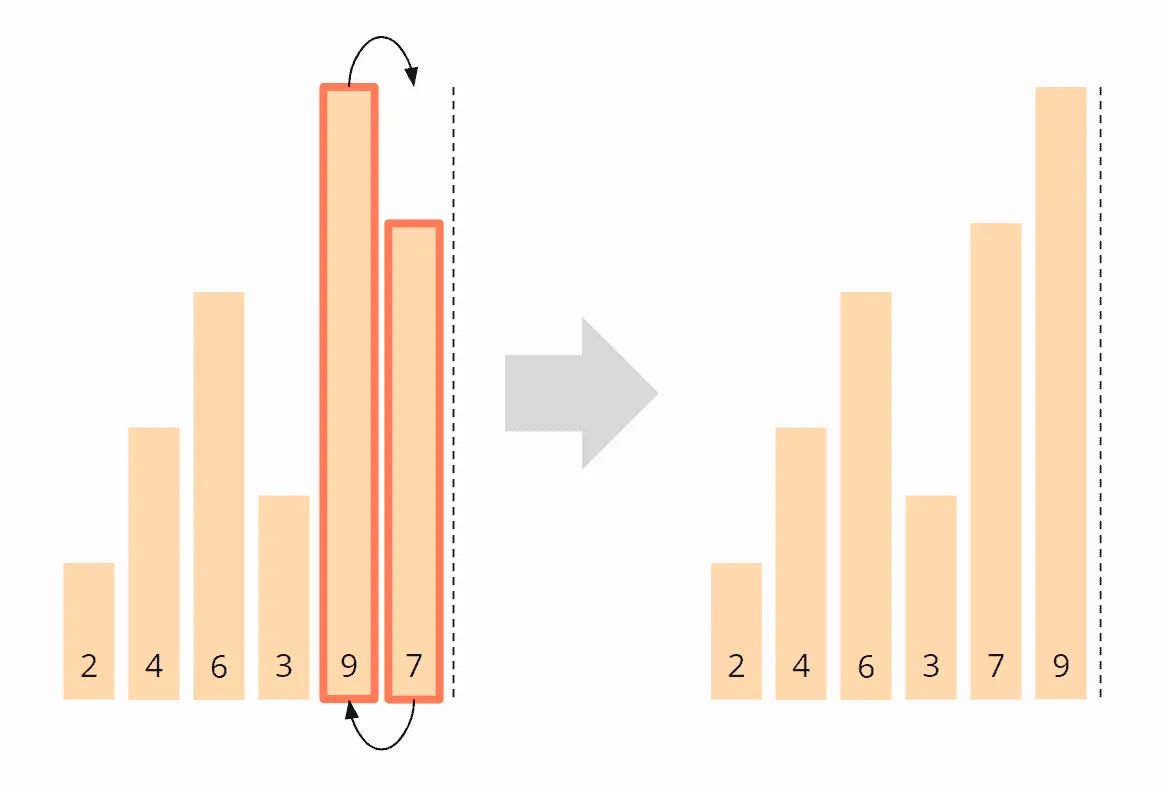
The 9 has reached its final position, and we move the border between the areas one field to the left:
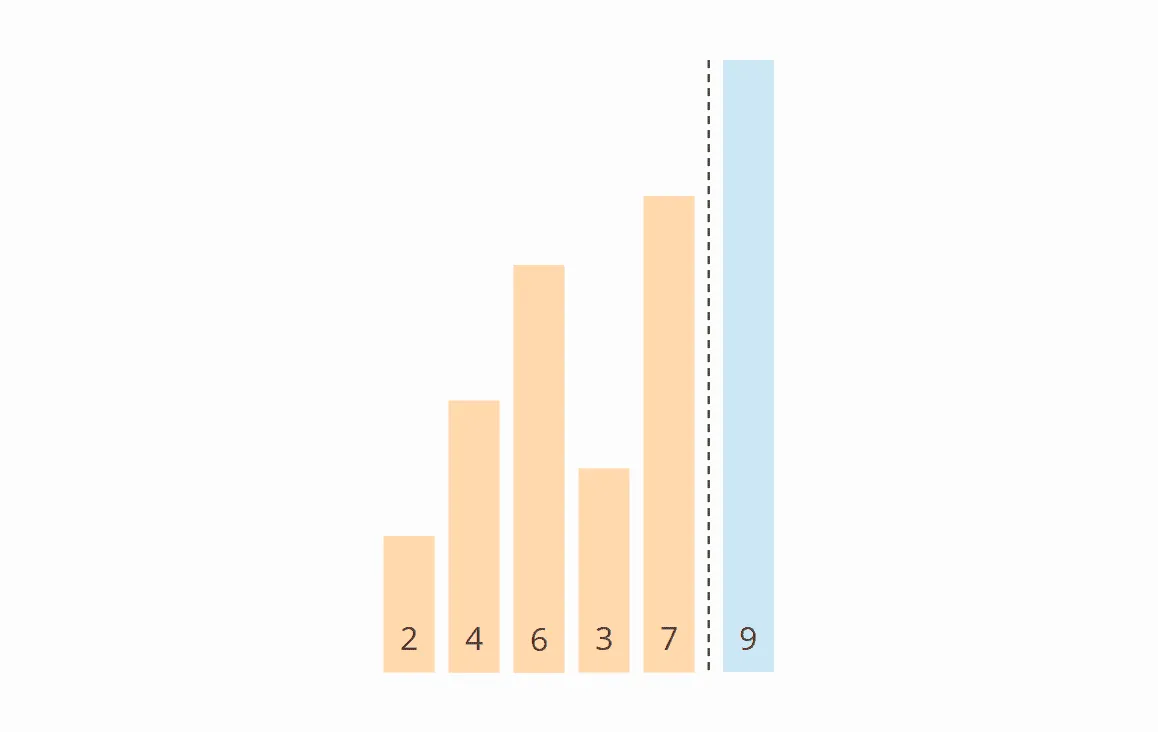
In the next iteration, this boundary shows us up to which position the elements have to be compared. By the way, the area boundary only exists in the optimized version of Bubble Sort. In the original variant, it is missing. Consequently, in every iteration, the comparison is performed unnecessarily until the end of the array.
Iteration 2
We start again at the beginning of the array and compare the 2 with the 4. These are in the correct order and need not be swapped.
The same applies to the 4 and the 6.
The 6 and the 3, however, must be swapped to be in the correct order:
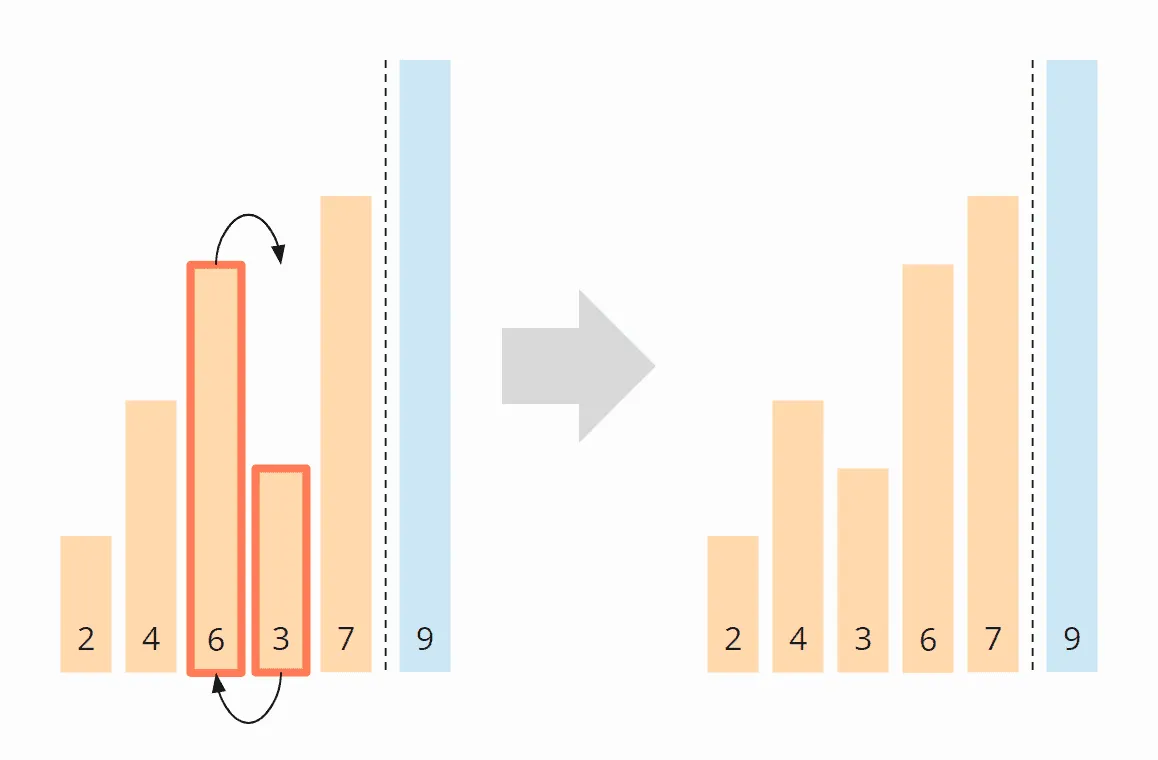
The 6 and the 7 are in the right order and do not need to be swapped. We do not need to compare further since the 9 is already in the sorted area.
Finally, we move the area boundary one position to the left again so that we don’t have to look at the last two elements, the 7 and the 9, any further.
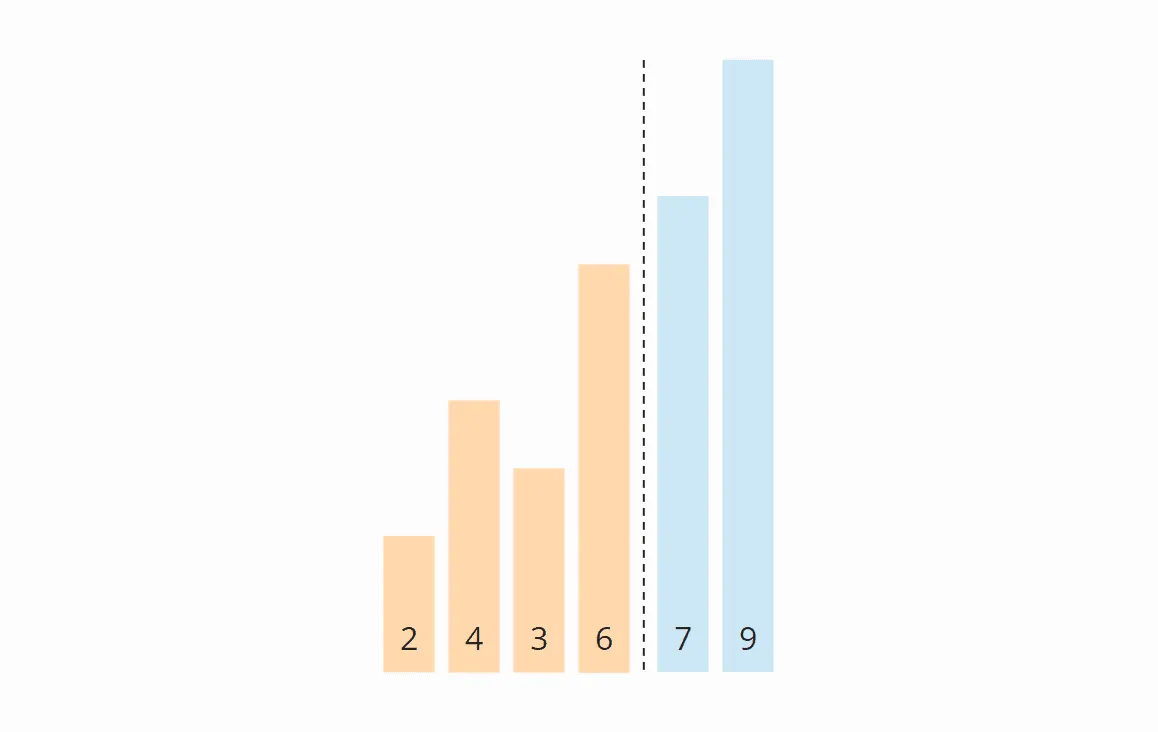
Iteration 3
Again we start at the beginning of the array. The 2 and the 4 are positioned correctly to each other. The 4 and the 3 must be swapped:
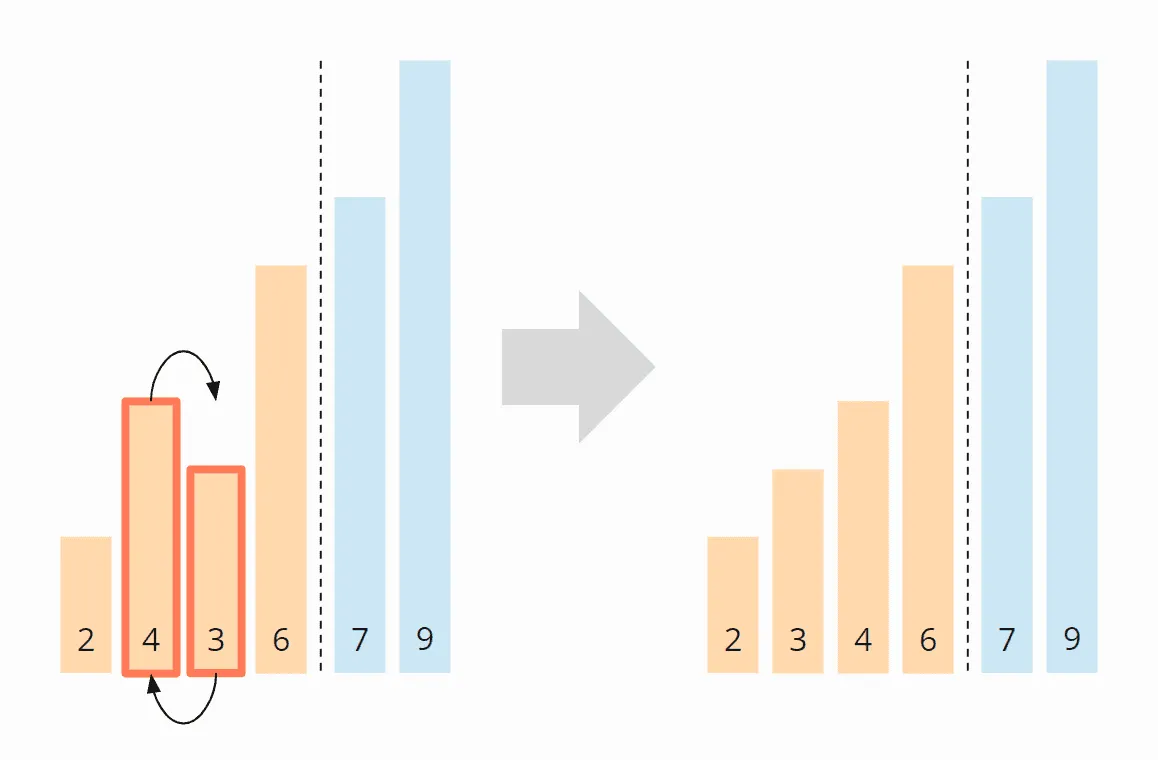
The 4 and the 6 do not have to be swapped. The 7 and the 9 are already sorted. So this iteration is already finished, and we move the area border to the left:
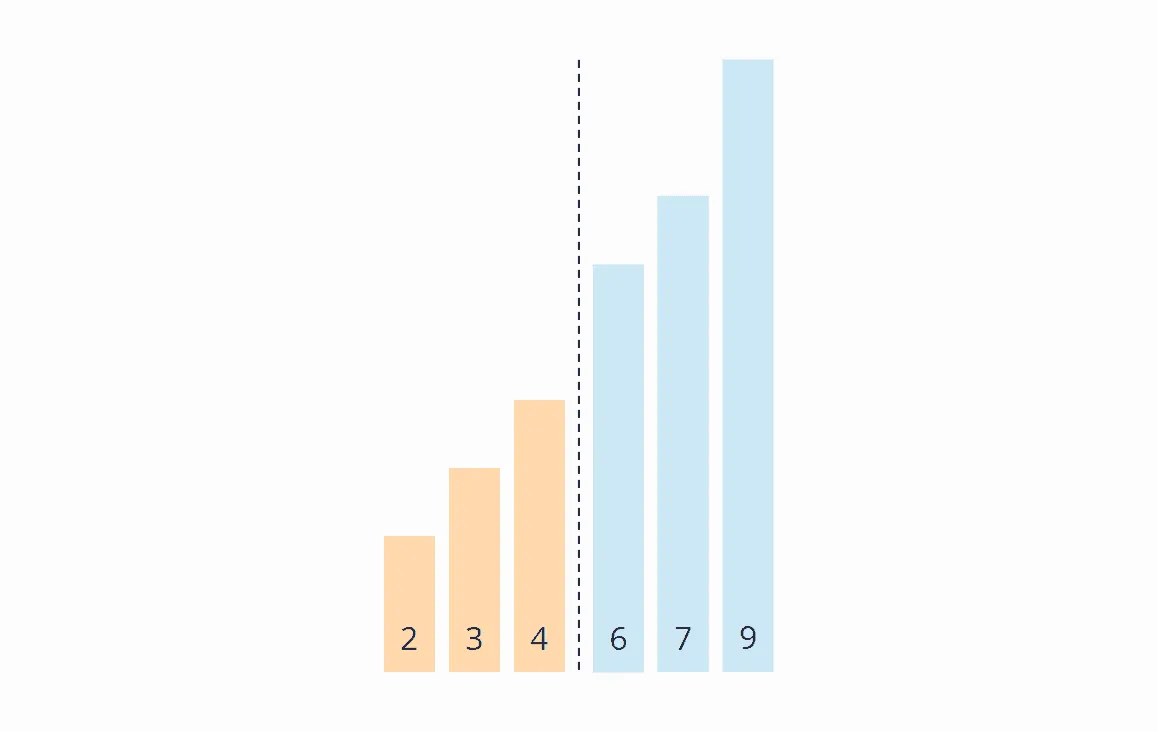
Iteration 4
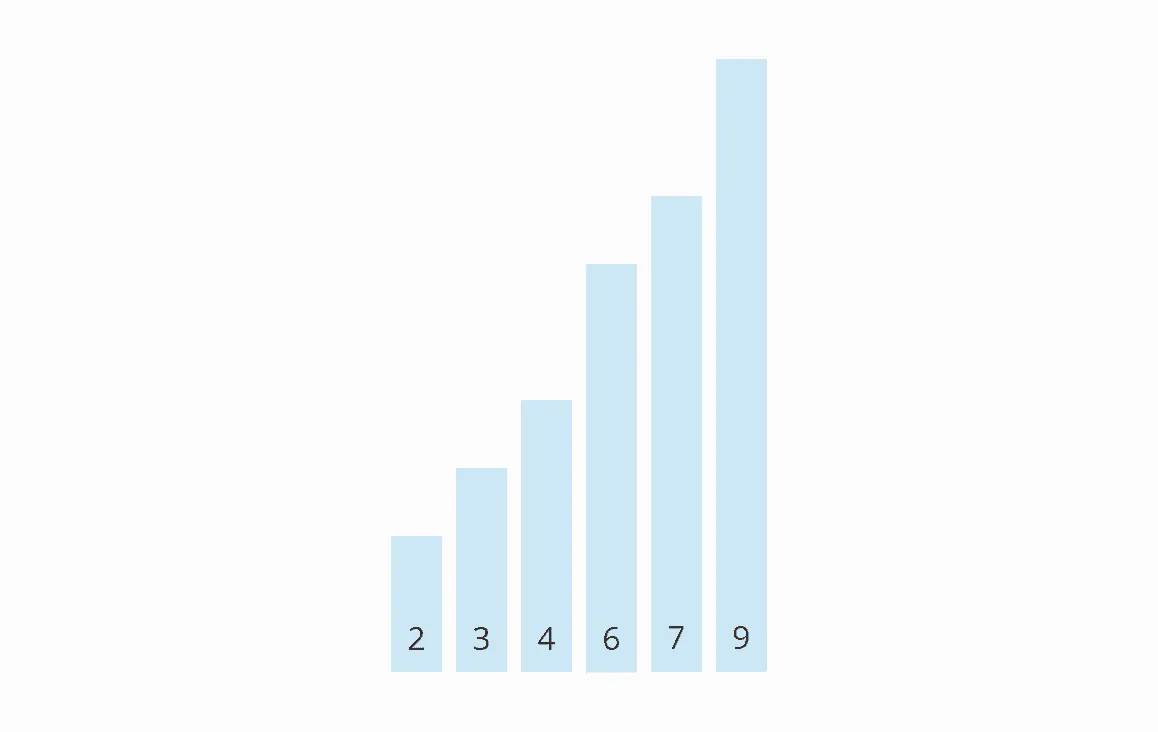
We start again at the beginning of the array. In the unsorted area, neither the 2 and 3 nor the 3 and 4 have to be swapped. Now all elements are sorted, and we can finish the algorithm.
Origin of the Name
When we animate the previous example’s swapping operations, the elements gradually rise to their target positions – similar to bubbles, hence the name “Bubble Sort”:
Bubble Sort Java Source Code
Below you will find the optimized implementation of Bubble Sort described above.
In the first iteration, the largest element moves to the far right. In the second iteration, the second-largest moves to the second last position. And so on. Therefore, in every iteration, we have to compare one element less than in the previous iteration.
In the previous section’s example, I had represented this by the area boundary, which moves one position to the left after each iteration.
Therefore, in the outer loop, we decrement the value max, starting at elements.length - 1, by one in every iteration.
The inner loop then compares two elements with each other up to the position max and swaps them if the left element is larger than the right one.
If no elements were swapped in an iteration (i.e., swapped is false), the algorithm ends prematurely.
public class BubbleSortOpt1 {
  public static void sort(int[] elements) {
    for (int max = elements.length - 1; max > 0; max--) {
      boolean swapped = false;
      for (int i = 0; i < max; i++) {
        int left = elements[i];
        int right = elements[i + 1];
        if (left > right) {
          elements[i + 1] = left;
          elements[i] = right;
          swapped = true;
        }
      }
      if (!swapped) break;
    }
  }
}
The code shown is slightly different from the BubbleSortOpt1 class in the GitHub repository. The class in the repository implements the SortAlgorithm interface to be interchangeable within the test framework.
The non-optimized algorithm – which compares the elements until the end in each iteration – can be found in the class BubbleSort.
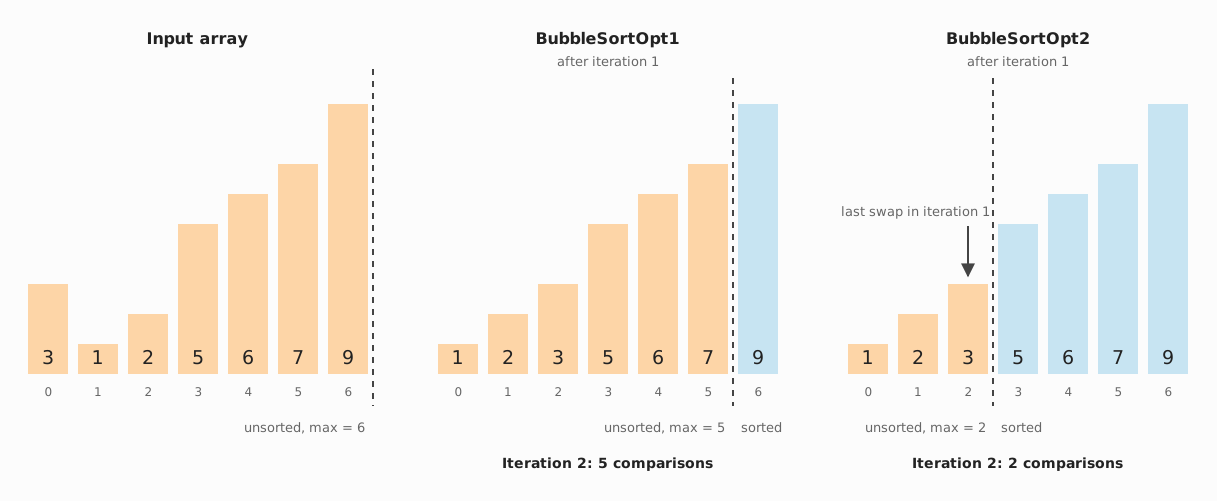
In the class BubbleSortOpt2, you find a theoretically even more optimized algorithm. After the nth iteration, it is possible that not only the last n elements are sorted, but more than that – depending on how the elements were originally arranged.
Therefore, this variant does not count max down by 1, but, after each iteration, sets max to the position of the last swapped element.
The following figure shows both variants after the first iteration of sorting the array [3, 1, 2, 5, 6, 7, 9]. On the left, max has been decremented by one; on the right, max is set to 2 because there was no further swap after position 2. So in the next iteration, BubbleSortOpt1 will perform another five comparisons, BubbleSortOpt2 only two.
However, the CompareBubbleSorts test shows that this variant brings hardly any advantage in practice. The test sorts 40,000 unsorted elements with each variant, 100 times after 15 warm-up rounds. On an Intel Core i7-12700H, the result is:
----- Results after 100 iterations-----
BubbleSort     -> fastest: 1,964.758 ms, median: 1,996.803 ms
BubbleSortOpt1 -> fastest: 1,620.518 ms, median: 1,655.024 ms
BubbleSortOpt2 -> fastest: 1,567.071 ms, median: 1,590.026 ms
And on an Apple M5 Pro:
----- Results after 100 iterations-----
BubbleSort     -> fastest:   937.231 ms, median:   950.006 ms
BubbleSortOpt1 -> fastest:   591.295 ms, median:   650.216 ms
BubbleSortOpt2 -> fastest:   650.353 ms, median:   672.370 ms
On the i7-12700H, BubbleSortOpt2 is 4% faster than BubbleSortOpt1; on the M5 Pro, it is 3% slower. In the first version of this article from 2020, it was 13% slower on an Intel Core i7-8750H.
So the comparisons that the second optimized version saves hardly pay off. I assume that storing and repeatedly (within one iteration) updating the last swapped element’s position is more expensive than changing the swapped value at most once per iteration – and which of the two weighs more depends on the CPU.
The complete output of the test program is in the GitHub repository, for the i7-12700H, the M5 Pro, and the 2020 run.
Bubble Sort Time Complexity
We denote by n the number of elements to be sorted. In the example above, n = 6.
The two nested loops suggest that we are dealing with quadratic time, i.e., a time complexity of O(n²). This will be the case if both loops iterate to a value that grows linearly with n.
For Bubble Sort, this is not as easy to prove as for Insertion Sort or Selection Sort.
With Bubble Sort, we have to examine best, worst, and average case separately. We will do this in the following subsections.
Best Case Time Complexity
Let’s start with the most straightforward case: If the numbers are already sorted in ascending order, the algorithm will determine in the first iteration that no number pairs need to be swapped and will then terminate immediately.
The algorithm must perform n-1 comparisons; therefore:
The best-case time complexity of Bubble Sort is: O(n).
This holds only for the optimized variant with the swapped flag. The original variant without early termination runs all n – 1 iterations even on sorted input and is, therefore, O(n²) in the best case, too.
Worst Case Time Complexity
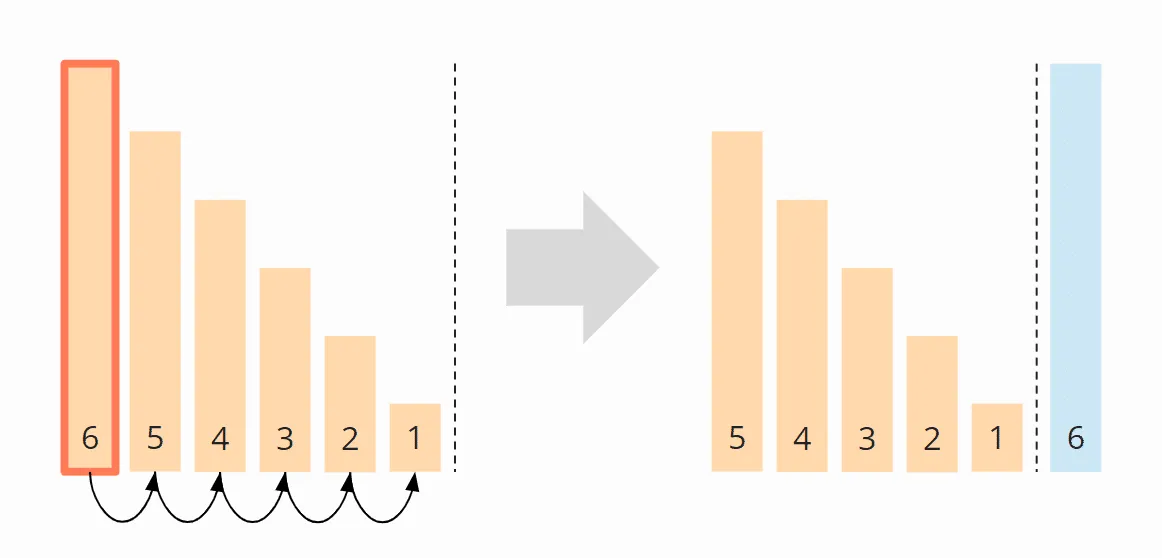
I will demonstrate the worst case with an example. Let’s assume we want to sort the descending array [6, 5, 4, 3, 2, 1] with Bubble Sort.
In the first iteration, the largest element, the 6, moves from far left to far right. I omitted the five single steps (swapping the pairs 6/5, 6/4, 6/3, 6/2, 6/1) in the figure:
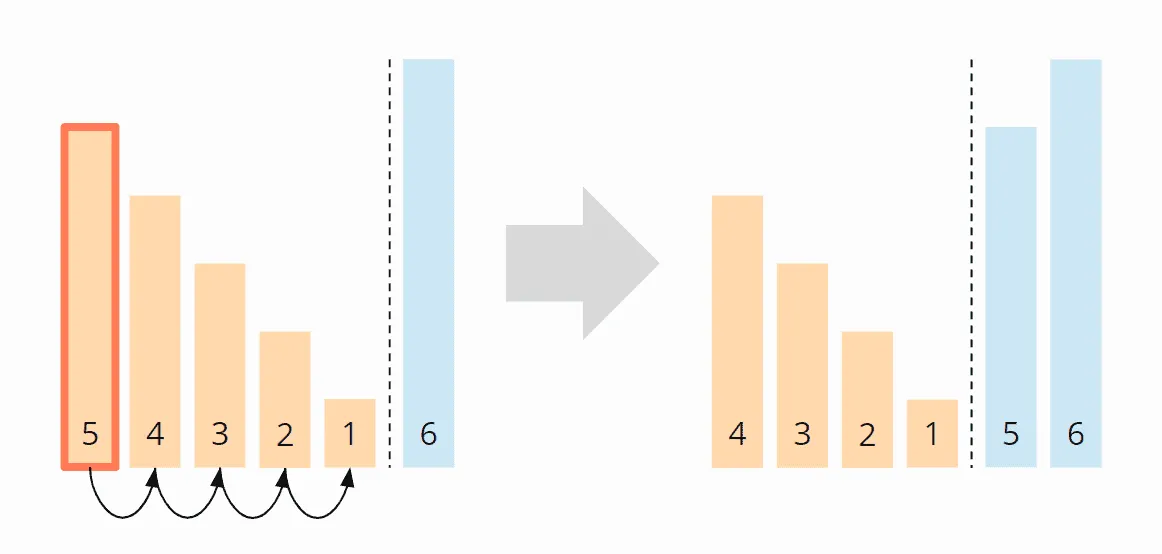
In the second iteration, the second largest element, the 5, is moved from the far left – via four intermediate steps – to the second last position:
In the third iteration, the 4 is pushed to the third last place – via three intermediate steps.
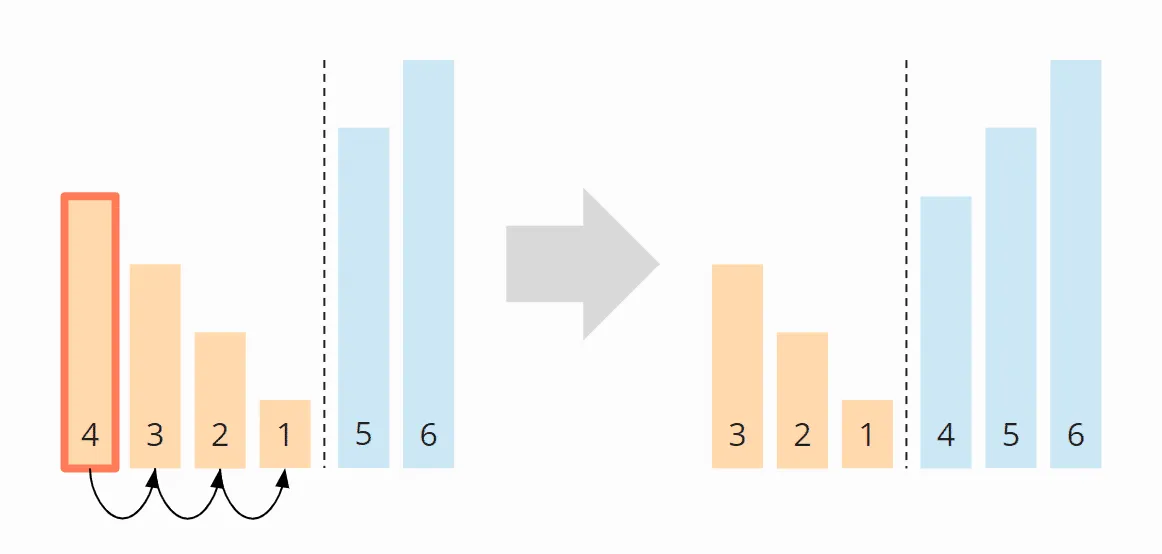
In the fourth iteration, the 3 is moved – via two single steps – to its final position:
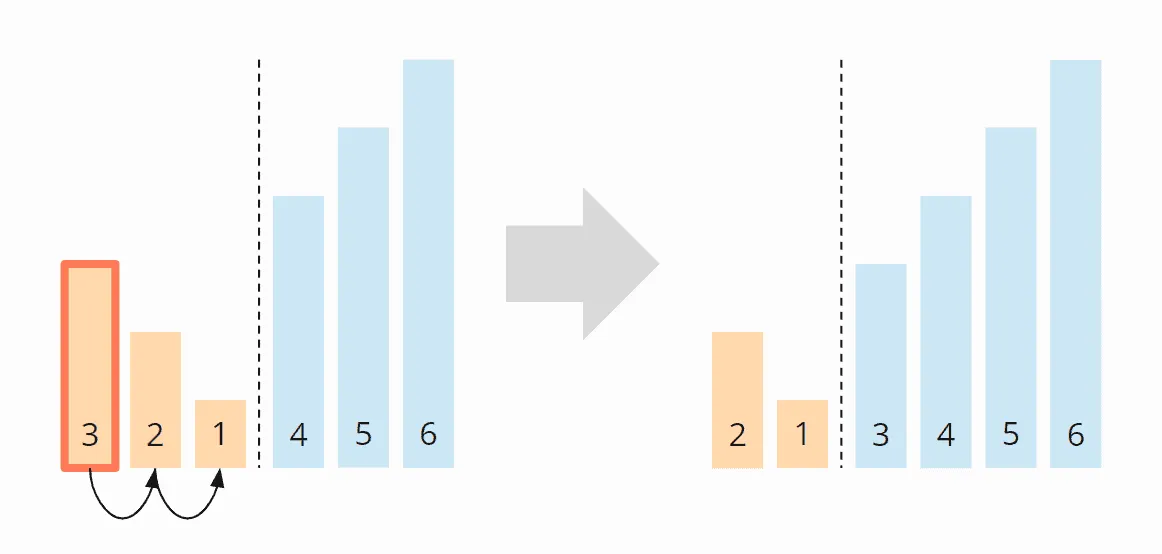
And finally, the 2 and the 1 are swapped:
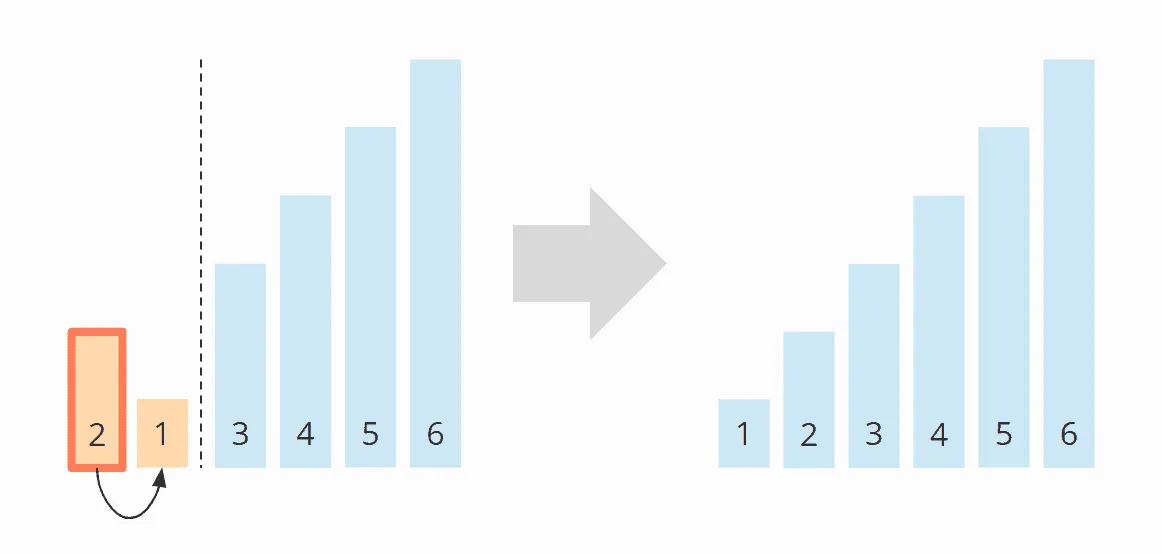
So in total we have 5 + 4 + 3 + 2 + 1 = 15 comparison and exchange operations.
We can also calculate this as follows:
Six elements times five comparison and exchange operations; divided by two, since on average across all iterations, half of the elements are compared and swapped:
6 × 5 × ½ = 30 × ½ = 15
If we replace 6 with n, we get:
n × (n – 1) × ½
When multiplied, that gives us:
½ (n² – n)
The highest power of n in this term is n²; therefore:
The worst-case time complexity of Bubble Sort is: O(n²).
Average Time Complexity
Unfortunately, the average time complexity of Bubble Sort cannot – in contrast to most other sorting algorithms – be explained in an illustrative way.
Without proving this mathematically (this would go beyond the scope of this article), one can roughly say that in the average case, one has about half as many exchange operations as in the worst case since about half of the elements are in the correct position compared to the neighboring element. So the number of exchange operations is:
¼ (n² – n)
It becomes even more complicated with the number of comparison operations, which amounts to (source: this German Wikipedia article; the English version doesn’t cover this):
½ (n² – n × ln(n) – (γ + ln(2) – 1) × n) + O(√n)
Here, γ is the Euler–Mascheroni constant, about 0.5772.
In both terms, the highest power of n is again n²; therefore:
The average-case time complexity of Bubble Sort is: O(n²).
Runtime of the Java Bubble Sort Example
Let’s verify the theory with a test! The GitHub repository contains the program UltimateTest, which measures Bubble Sort and all other sorting algorithms of this article series:
- for array sizes from 1,024 elements, doubled each time, until a sort takes longer than 20 seconds (up to 536,870,912 elements at most);
- with unsorted, ascending and descending sorted elements;
- with two warm-up rounds so that the HotSpot compiler can optimize the code.
For Bubble Sort, I show the results of two computers, because they behave differently in two points that this article explains: an Intel Core i7-12700H (x86) and an Apple M5 Pro (arm64). Here are the times for unsorted and descending sorted elements (only an excerpt for the sake of clarity):
| n | i7: unsorted | i7: descending | M5: unsorted | M5: descending |
|---|---|---|---|---|
| ... | ... | ... | ... | ... |
| 8,192 | 44.14 ms | 37.11 ms | 17.59 ms | 43.93 ms |
| 16,384 | 237.29 ms | 150.37 ms | 69.27 ms | 176.46 ms |
| 32,768 | 1,070.42 ms | 601.36 ms | 349.71 ms | 705.84 ms |
| 65,536 | 4,507.21 ms | 2,410.48 ms | 2,381.79 ms | 2,835.76 ms |
| 131,072 | 18,509.36 ms | 9,625.46 ms | 12,009.12 ms | 11,337.42 ms |
And for ascending sorted elements:
| n | i7-12700H | M5 Pro |
|---|---|---|
| ... | ... | ... |
| 8,192 | 0.007 ms | 0.004 ms |
| 131,072 | 0.059 ms | 0.038 ms |
| 262,144 | 0.102 ms | 0.068 ms |
| ... | ... | ... |
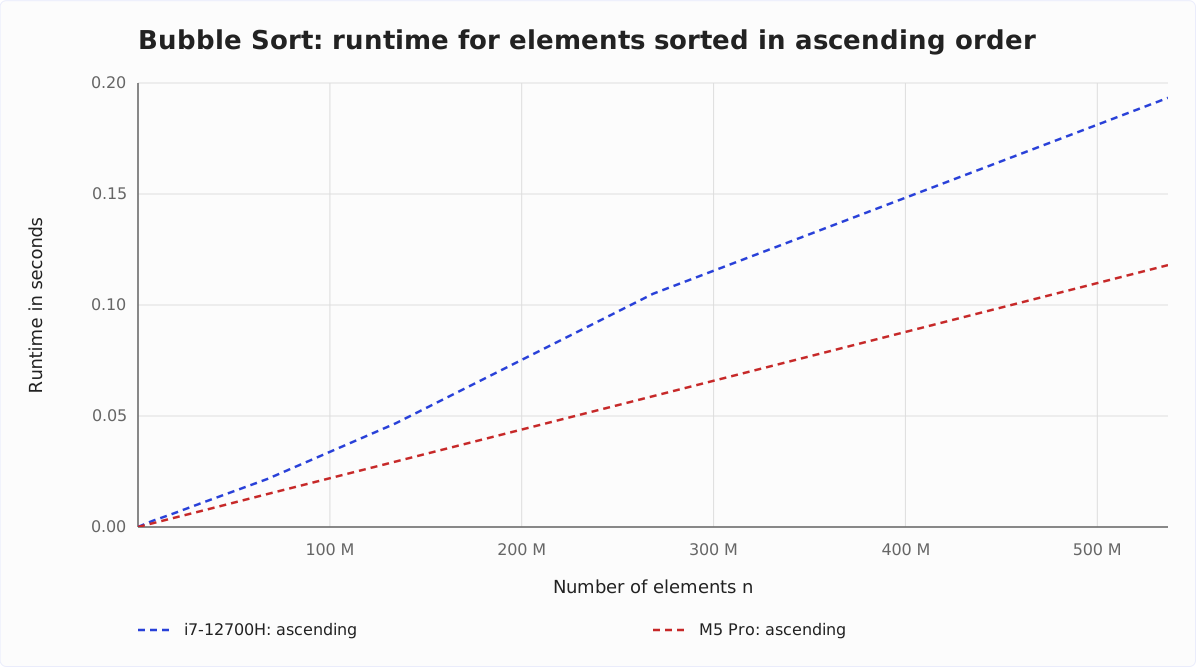
| 536,870,912 | 193.332 ms | 117.977 ms |
Here are the measured values as a diagram, in blue for the i7-12700H, in red for the M5 Pro:
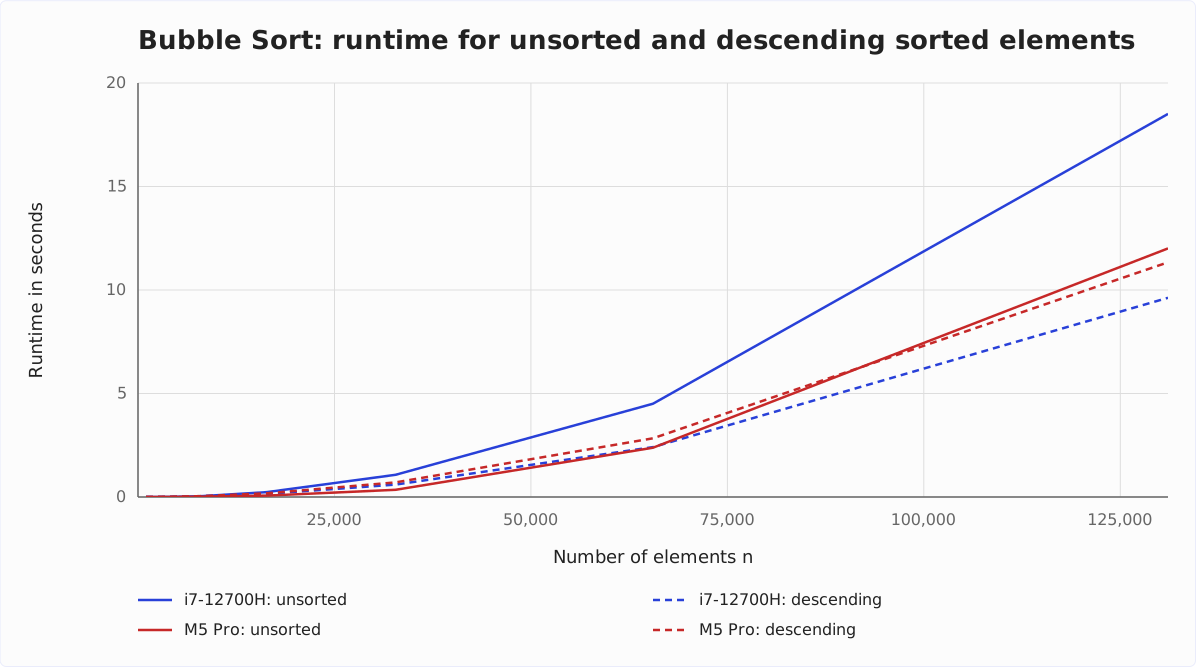
With ascending sorted elements, Bubble Sort is so fast that the lines would not rise above the x-axis in this diagram. Therefore, here is the best case separately, up to 536,870,912 elements:
You can see:
- For descending sorted elements, the runtime quadruples when doubling the input quantity – on both computers (factor 3.99 to 4.05).
- For unsorted elements, it grows faster: on the i7-12700H by a factor of 5.38 from 8,192 to 16,384 elements, then decreasing to 4.11; on the M5 Pro first by 3.94 and then by 5.05, 6.81, and 5.04.
- For elements sorted in ascending order, the runtime increases linearly and is orders of magnitude smaller than for unsorted elements: about 0.22 ns per element on the M5 Pro from 1,048,576 elements on, 0.32 to 0.39 ns on the i7-12700H from 262,144 elements on.
- On the i7-12700H, unsorted elements take 1.19 to 1.92 times as long as descending sorted ones (in 2020, it was 1.75 to 2.31 times). On the M5 Pro, it is the other way around: descending sorted elements take 1.19 to 2.55 times as long as unsorted ones up to 65,536 elements; only at 131,072 elements are they slightly faster.
The first and third observations meet expectations.
But why does the runtime for unsorted elements grow faster than quadratically? And why, on the i7-12700H, is the runtime in the average case so much higher than in the worst case? Wouldn’t we have to have about half as many swap operations there and at least minimally fewer comparisons – and accordingly rather half the time than twice?
Swap and Comparison Operations in Average and Worst Case
To check this, I use the program CountOperations to display the number of different operations. I’ve summarized the results for unsorted and descending sorted elements in the following table:
| n | Swaps unsorted | Swaps descending | Comparisons unsorted | Comparisons descending |
|---|---|---|---|---|
| ... | ... | ... | ... | ... |
| 128 | 8,050 | 16,256 | 8,136 | 8,255 |
| 256 | 31,854 | 65,280 | 32,893 | 32,895 |
| 512 | 128,340 | 261,632 | 130,767 | 131,327 |
| 1,024 | 528,004 | 1,047,552 | 524,475 | 524,799 |
| 2,048 | 2,111,760 | 4,192,256 | 2,097,546 | 2,098,175 |
| ... | ... | ... | ... | ... |
The results confirm the assumption: With unsorted elements, we have about half as many swap operations and slightly fewer comparisons than with elements sorted in descending order.
Why Is Bubble Sort Faster on x86 for Elements Sorted in Descending Order Than for Unsorted Elements?
How is it possible that, on the i7-12700H, Bubble Sort is so much faster with elements sorted in descending order than with randomly ordered elements despite twice as many exchange operations?
The reason for this discrepancy can be found in “branch prediction”:
If the elements are sorted in descending order, the comparison if (left > right) yields true for every pair within an iteration.
If the branch prediction assumes that the result of a comparison is the same as that of the previous one, it is always right – with a single exception per iteration: at the end of the inner loop. This allows the CPU’s instruction pipeline to be fully utilized most of the time.
On the other hand, with unsorted data, no reliable predictions can be made about the outcome of the comparison, so that the pipeline must often be deleted and refilled.
This can be shown with a variant of BubbleSortOpt1 that has no data-dependent branch at all. It always writes both elements back and calculates, instead of deciding, which of them goes to the left:
int left = elements[i];
int right = elements[i + 1];
int mask = (right - left) >> 31; // -1 if right < left, else 0
int delta = (right - left) & mask;
elements[i] = left + delta;
elements[i + 1] = right - delta;
swapped |= mask;
On both computers, the runtime of this variant grows by a factor of 3.97 to 4.03 per doubling from 8,192 to 131,072 elements – i.e., exactly quadratically – and unsorted elements take just as long as descending sorted ones: 9.03 s versus 9.07 s for 131,072 elements on the i7-12700H, and 10.60 s versus 10.59 s on the M5 Pro. Without the branch, the growth beyond n² disappears, and so does the difference between the two input orders. The raw data of this measurement – 10 runs each after two warm-up runs, JDK 27 – is in the GitHub repository for the i7-12700H and the M5 Pro.
On the i7-12700H, the branch-free variant is also faster than BubbleSortOpt1 for unsorted elements, 1.28 times as fast at 8,192 elements and 2.05 times at 131,072.
And Why Not on the Apple M5 Pro?
On the M5 Pro, BubbleSortOpt1 sorts 8,192 unsorted elements in 18 ms – the branch-free variant, which never has to pay for a misprediction, takes 41 ms. If the M5 Pro often mispredicted the comparison for random data, BubbleSortOpt1 would be slower than the branch-free variant, not more than twice as fast. So it predicts the comparison correctly most of the time.
For small arrays, the swap operations therefore dominate on the M5 Pro, and there are twice as many of them with descending sorted elements – which is why they take 2.50 times as long at 8,192 elements. The i7-12700H shows the same effect for even smaller arrays: at 2,048 and 4,096 elements, descending sorted elements take 1.28 and 1.39 times as long there as unsorted ones.
The larger the array, the more often the prediction fails with unsorted elements. That is why their runtime grows faster than quadratically on the M5 Pro, too – from 16,384 elements on, even more strongly than on the i7-12700H – until they are slightly slower than descending sorted elements at 131,072. At this size, the branch-free variant is 1.13 times as fast as BubbleSortOpt1 on the M5 Pro as well.
The measurements do not show why the M5 Pro predicts the comparisons of small arrays so well.
Other Characteristics of Bubble Sort
This section deals with the space complexity, stability, and parallelizability of Bubble Sort.
Space Complexity of Bubble Sort
Bubble Sort requires no additional memory space apart from the loop variable max, and the auxiliary variables swapped, left, and right.
The space complexity of Bubble Sort is, therefore, O(1).
Stability of Bubble Sort
By always comparing two adjacent elements with each other – and only swapping them if the left element is larger than the right element – elements with the same key can never swap positions relative to each other.
That would require two elements to swap places across more than one position (as it happens with Selection Sort). With Bubble Sort, this cannot occur.
Bubble Sort is, therefore, a stable sorting algorithm.
Parallelizability of Bubble Sort
There are two approaches to parallelize Bubble Sort:
Approach 1 “Odd-Even Sort”
You compare in parallel the first with the second element, the third with the fourth, the fifth with the sixth, etc. and swap the respective elements if the left one is larger than the right one.
Then you compare the second element with the third, the fourth with the fifth, the sixth with the seventh, and so on.
These two steps are alternated until no more elements are swapped in either step:
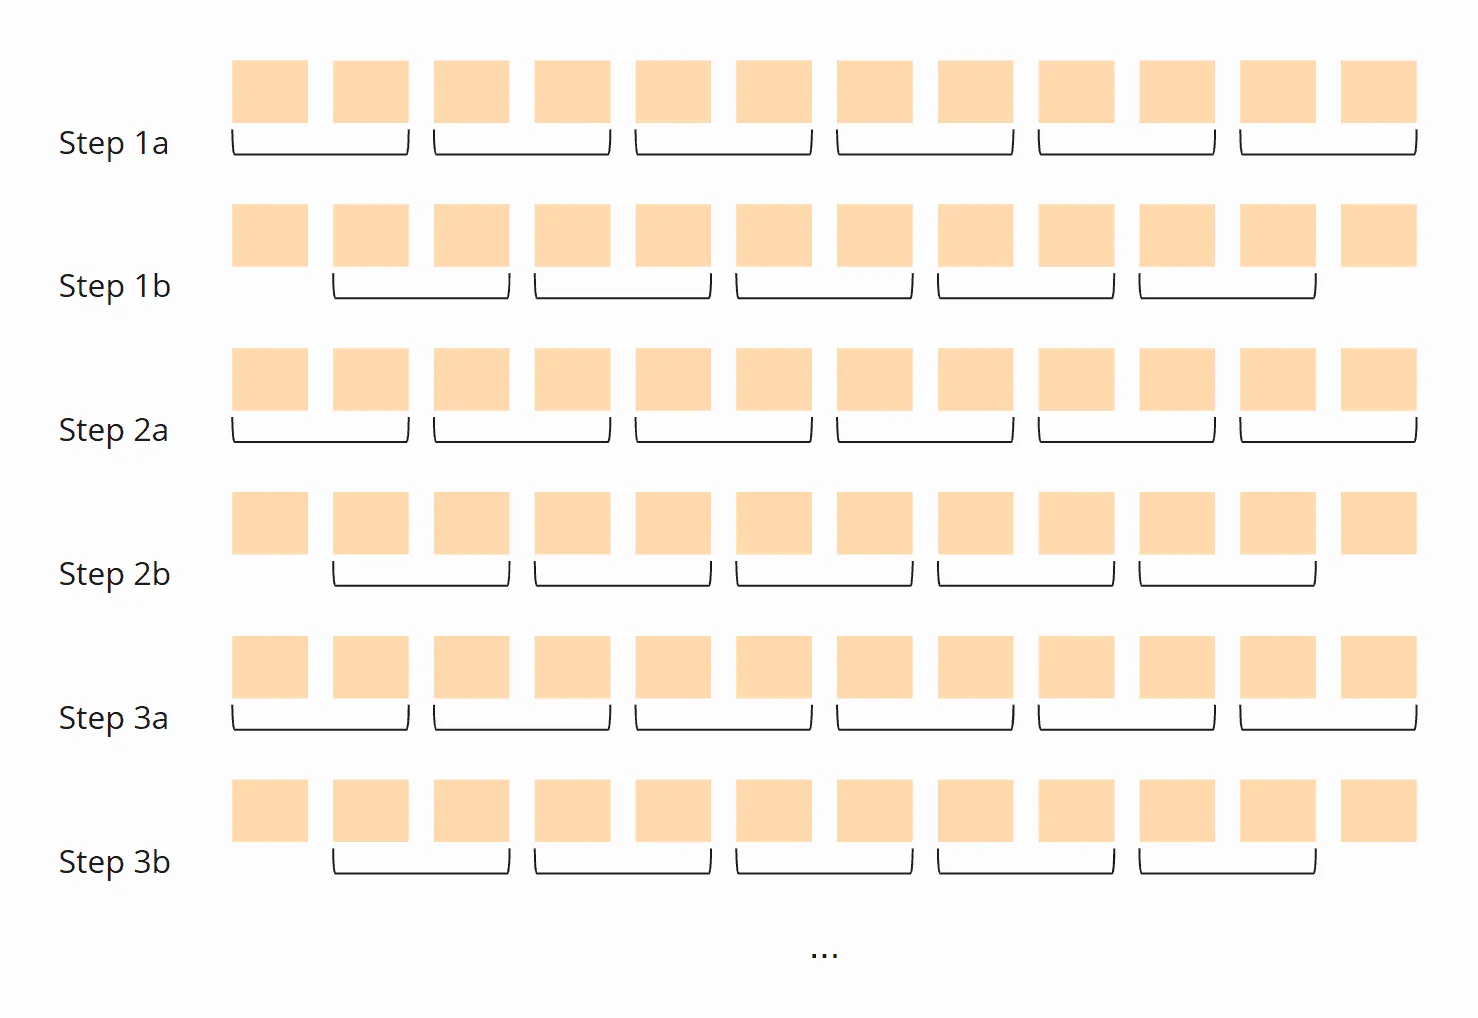
This algorithm is also called “Odd-even sort”.
You can find the source code in the BubbleSortParallelOddEven class in the GitHub repository.
The synchronization between the steps (the threads may not start with a step until all threads have finished the previous step) is realized with a Phaser.
Approach 2 “Divide and Conquer”
You divide the array to be sorted into as many areas (“partitions”) as you have CPU cores available.
Now you perform one Bubble Sort iteration in all partitions in parallel. Wait until all threads are finished, and then compare the last element of one partition with the first of the next partition. When all threads are finished, the process starts again.
Repeat these steps until no more elements are swapped in all threads:
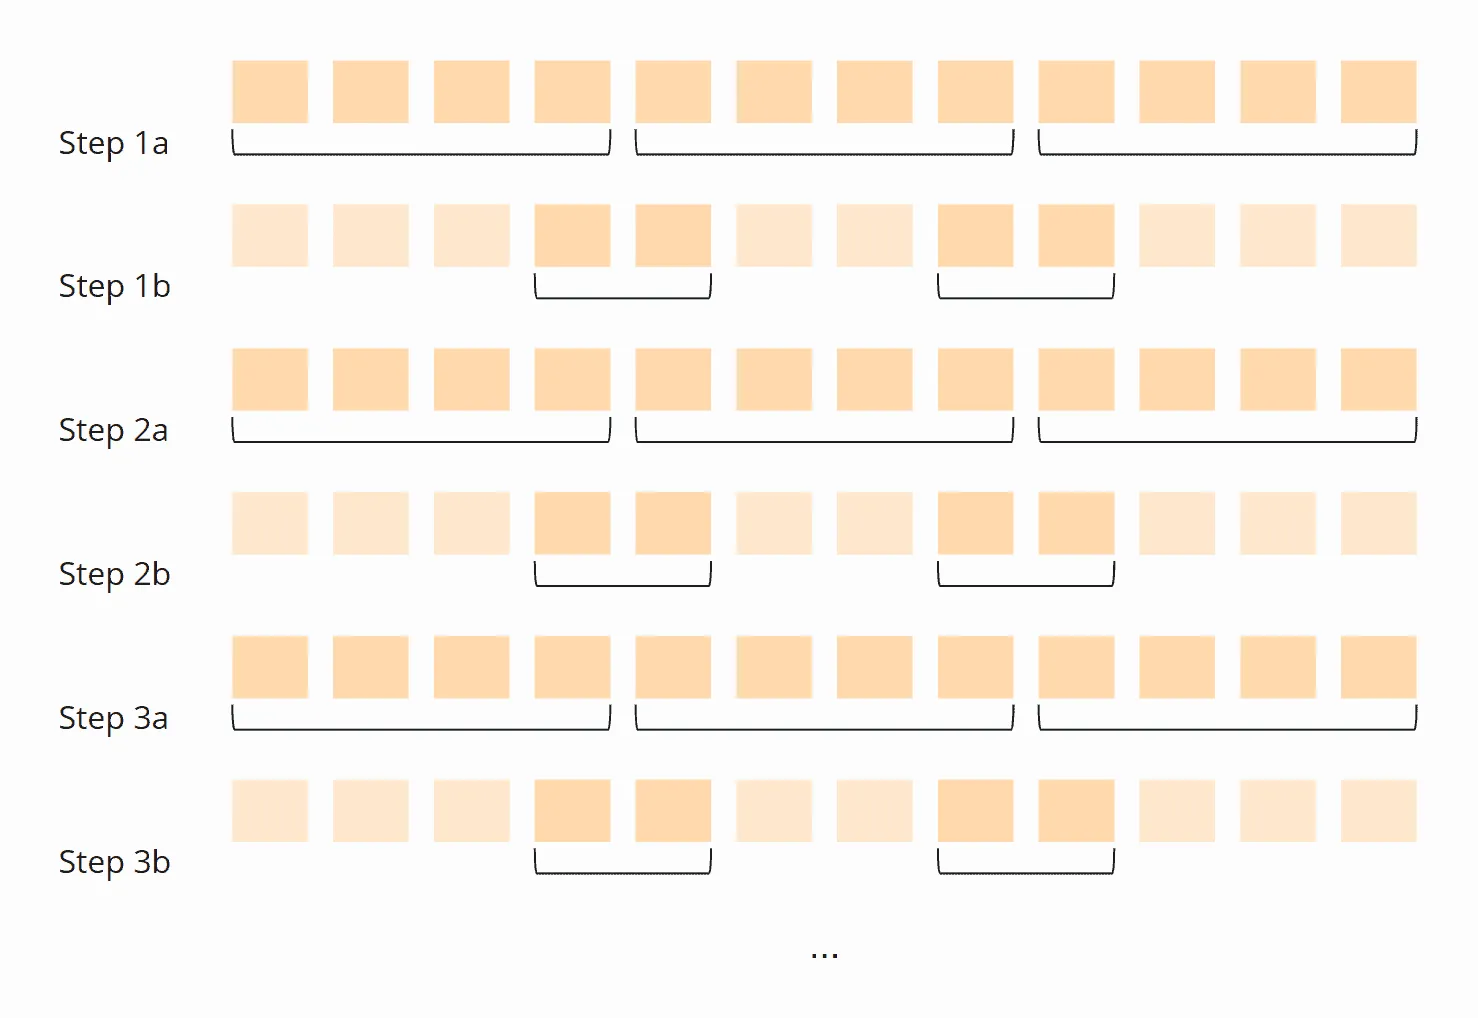
You can find the source code for the algorithm in the BubbleSortParallelDivideAndConquer class in the GitHub repository.
Again, a Phaser is used to synchronize the threads. In fact, much of the code of both algorithms is the same, since the array is also divided into partitions for the odd-even approach. I moved the shared code to the abstract base class BubbleSortParallel.
Parallel Bubble Sort: Performance
I compare the performance of the parallel variants with the CompareBubbleSorts test mentioned above, i.e., with 40,000 unsorted elements. Here is the result for the parallel algorithms, compared to BubbleSortOpt1, on the Intel Core i7-12700H:
----- Results after 100 iterations-----
BubbleSortOpt1                     -> fastest: 1,620.518 ms, median: 1,655.024 ms
BubbleSortParallelOddEven          -> fastest:   346.763 ms, median:   418.541 ms
BubbleSortParallelDivideAndConquer -> fastest:   705.699 ms, median:   812.285 ms
And on the Apple M5 Pro:
----- Results after 100 iterations-----
BubbleSortOpt1                     -> fastest:   591.295 ms, median:   650.216 ms
BubbleSortParallelOddEven          -> fastest: 2,160.888 ms, median: 2,268.396 ms
BubbleSortParallelDivideAndConquer -> fastest: 4,289.005 ms, median: 4,486.726 ms
On the i7-12700H, the “odd-even” variant is thus 3.95 times as fast as the sequential version, the “divide-and-conquer” approach 2.04 times. Three repetitions of the test gave 3.99 to 4.40 and 2.00 to 2.17.
On the M5 Pro, both parallel variants are slower than the sequential one: “odd-even” takes 3.49 times as long, “divide-and-conquer” 6.90 times.
Both parallel variants use as many threads as the JVM reports processors – 20 on the i7-12700H, 18 on the M5 Pro. How their speed depends on this number is shown by a second measurement in which I limited the number of processors with the JVM option -XX:ActiveProcessorCount (median of 20 runs, runtimes in milliseconds):
| Processors | Odd-even i7 | Odd-even M5 | D&C i7 | D&C M5 |
|---|---|---|---|---|
| 2 | 461 | 398 | 1,815 | 836 |
| 4 | 359 | 530 | 938 | 1,024 |
| 6 | 246 | 640 | 634 | 1,247 |
| 8 | 259 | 1,106 | 591 | 2,141 |
| 12 | 284 | 1,327 | 597 | 2,577 |
| 16 | 327 | 1,917 | 742 | 3,811 |
| 20 / 18 | 369 | 2,279 | 765 | 4,523 |
The sequential BubbleSortOpt1 needs 1,644 to 1,661 ms on the i7-12700H and 612 to 643 ms on the M5 Pro, regardless of the number of processors.
On the i7-12700H, “odd-even” is fastest with 6 processors: 6.71 times as fast as BubbleSortOpt1 – almost exactly as on the 6-core laptop of the first version of this article from 2020, where it was 6.6 times as fast. With more processors, it gets slower again.
The “divide-and-conquer” approach is at best 2.78 times as fast (with 8 processors; in 2020, it was 3.1 times). This is probably because each thread only performs one comparison in the second sub-step of the iteration. This stands in contrast to the relatively high synchronization effort required by the Phaser.
On the M5 Pro, both variants get slower with every additional thread. “Odd-even” is faster than BubbleSortOpt1 only with 2 and 4 processors, “divide-and-conquer” never. Each phase of both algorithms ends at the Phaser, where all threads wait for the slowest one – and on the M5 Pro, this wait costs more the more threads it holds.
The raw data of this measurement is in the GitHub repository for the i7-12700H and the M5 Pro.
Summary
Bubble Sort is an easy-to-implement, stable sorting algorithm with a time complexity of O(n²) in the average and worst cases – and O(n) in the best case.
In practice, Bubble Sort plays no role: for small arrays, Insertion Sort is the better choice with half as many comparisons, and for large ones, it is the efficient algorithms starting in the next part.
You will find more sorting algorithms in this overview of all sorting algorithms and their characteristics in the first part of the article series.
Bubble Sort was the last simple sorting method of this article series; in the next part, we will enter the realm of efficient sorting methods, starting with Quicksort.
If you enjoyed this article, I’d appreciate a review on my ProvenExpert profile.